Peike Li
Research Scientist @ Google | Efficient AI for LLMs & Multimodal Generation
Biography
I am a Research Scientist at Google Research. My long-term goal is generalist models that can perceive, imagine, and act in both digital and physical worlds, and I believe the path there runs through efficiency: models that scale further on the same compute, and run fast enough to interact with the world in real time.
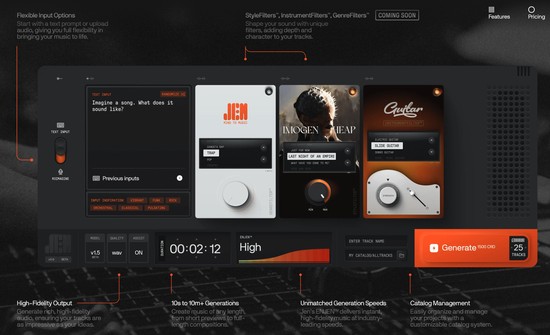
Today I work on efficient AI for LLMs and multimodal generative models: pretraining efficiency (Gemini, Gemma) and inference efficiency (Veo, SL2T). Before Google, I led the music-generation team behind JEN-1, and earlier interned at Alibaba (Qwen team), Baidu Research, and 360 Research.
I am currently exploring the intersection of Efficient AI, Multimodal AI, and System 2 Reasoning, specifically:
- Scaling unified transformers on internet-scale multimodal data to build high-fidelity generative world models.
- Making generation streaming and low-latency enough to run in real time—treating latency as a first-class research problem rather than an afterthought.
- Connecting multimodal generative models with causal and physical consistency as a path from passive generation toward agents that act.
I’m always happy to talk about efficient world models, video generation, multimodal LLMs, and embodied foundation models, and I welcome collaborations across industry and academia. Authorized to work in the US and Australia.
To accelerate the advent of machine intelligence and sustainable future
Interests
- Efficient AI ⚡
- LLM 🧠
- World Model 🌍
- Multimodal AI 🤖
- Generative AI 🎨
Education
-
PhD in Computer Science
University of Technology Sydney
-
Master of Engineering
Shanghai Jiao Tong University
-
Visiting Student
Karlsruher Institut für Technologie
-
Bachelor of Engineering
Shanghai Jiao Tong University